

Cost tab
What a run’s language model calls used and roughly what they cost, split by provider and model. Use it to see which model drove a run’s spend, or to check that cached input is being picked up.
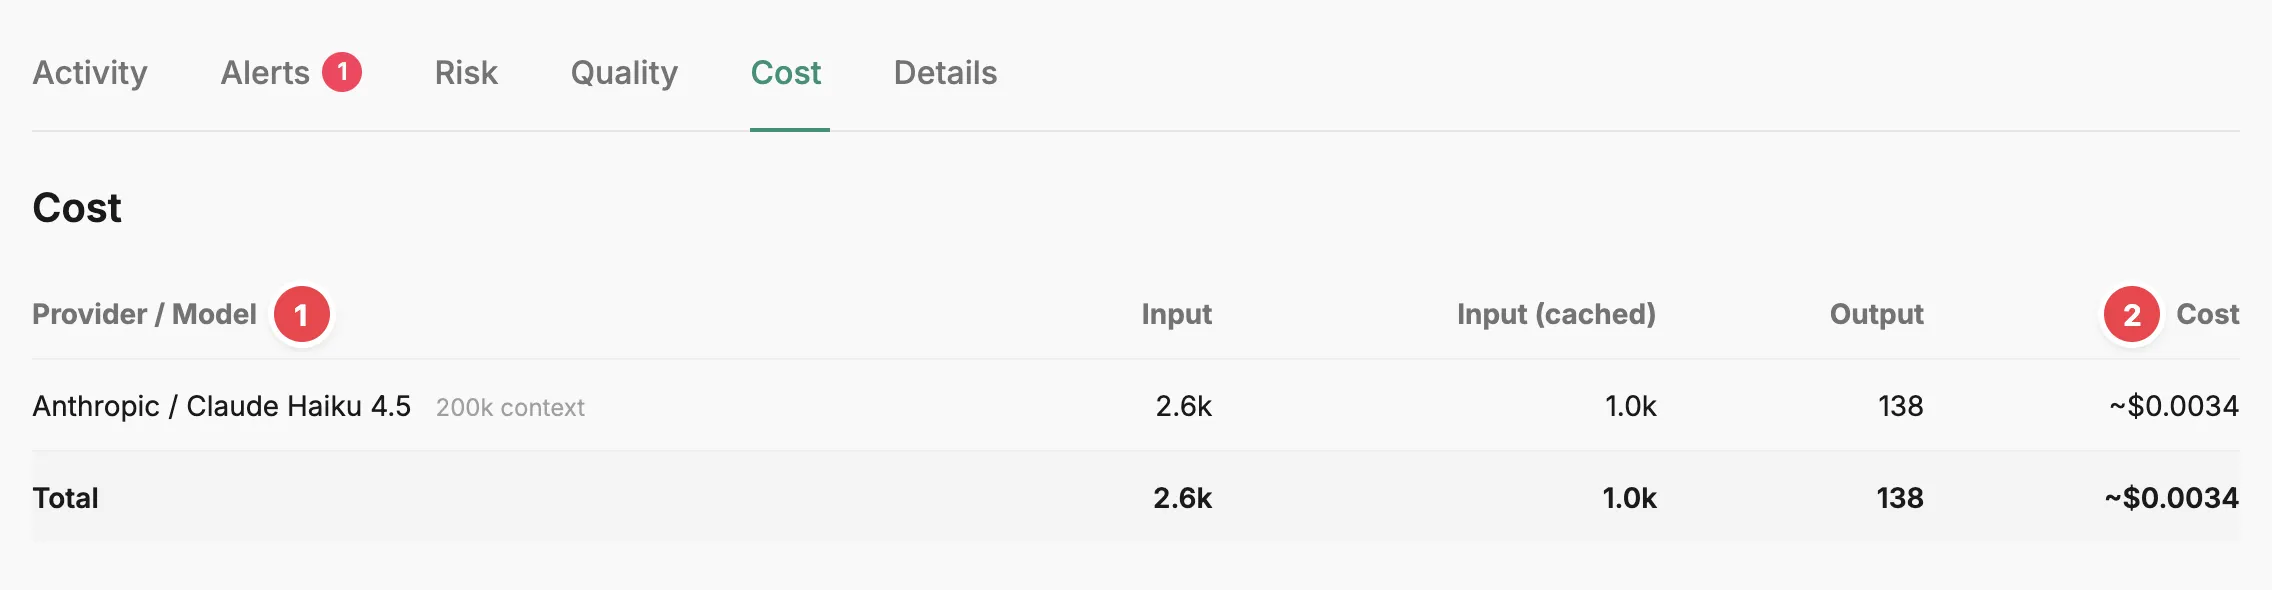
- Provider / Model - the model each row covers, with its context window.
- Cost - the estimated cost in US dollars.
The tab only appears when the run recorded token usage on language model spans from an integration Prefactor reads tokens from: the OpenClaw plugin, the AI SDK, and GitHub Copilot Chat. The same totals appear as the Cost breakdown cards above the tabs on the Agent instance page.
The table has one row per provider and model, then a Total row. Provider / Model uses the names from models.dev when it knows the model, with the model’s context window beside it, such as “200k context”. Input, Input (cached), and Output are token counts. The AI SDK doesn’t report cached input, so its rows show 0 there.
Cost is an estimate in US dollars, worked out from models.dev’s published prices for each model. Every non-zero cost starts with ~ to show it’s approximate. “free” means the model’s price is zero, and ”—” means models.dev has no price for the model. When one row shows ”—” and another has a cost above zero, the Total cost shows ”—” too, because a partial sum would understate the spend.
Related
Section titled “Related”- Agent instance page — the cost breakdown cards and the strip above the tabs.
- Agent instance page › Activity tab — token counts on each LLM call card.
- Span — what a span records, including the LLM spans the tokens come from.